Delivery fleets solve similar routing problems every day, yet solvers start each one from scratch. EARLI (Evolutionary Algorithm with Reinforcement Learning Initialization) trains a reinforcement learning agent on previous problems and uses its solutions to initialize a genetic algorithm. It routes 500 locations within one second, 10x faster than current solvers at the same solution quality.
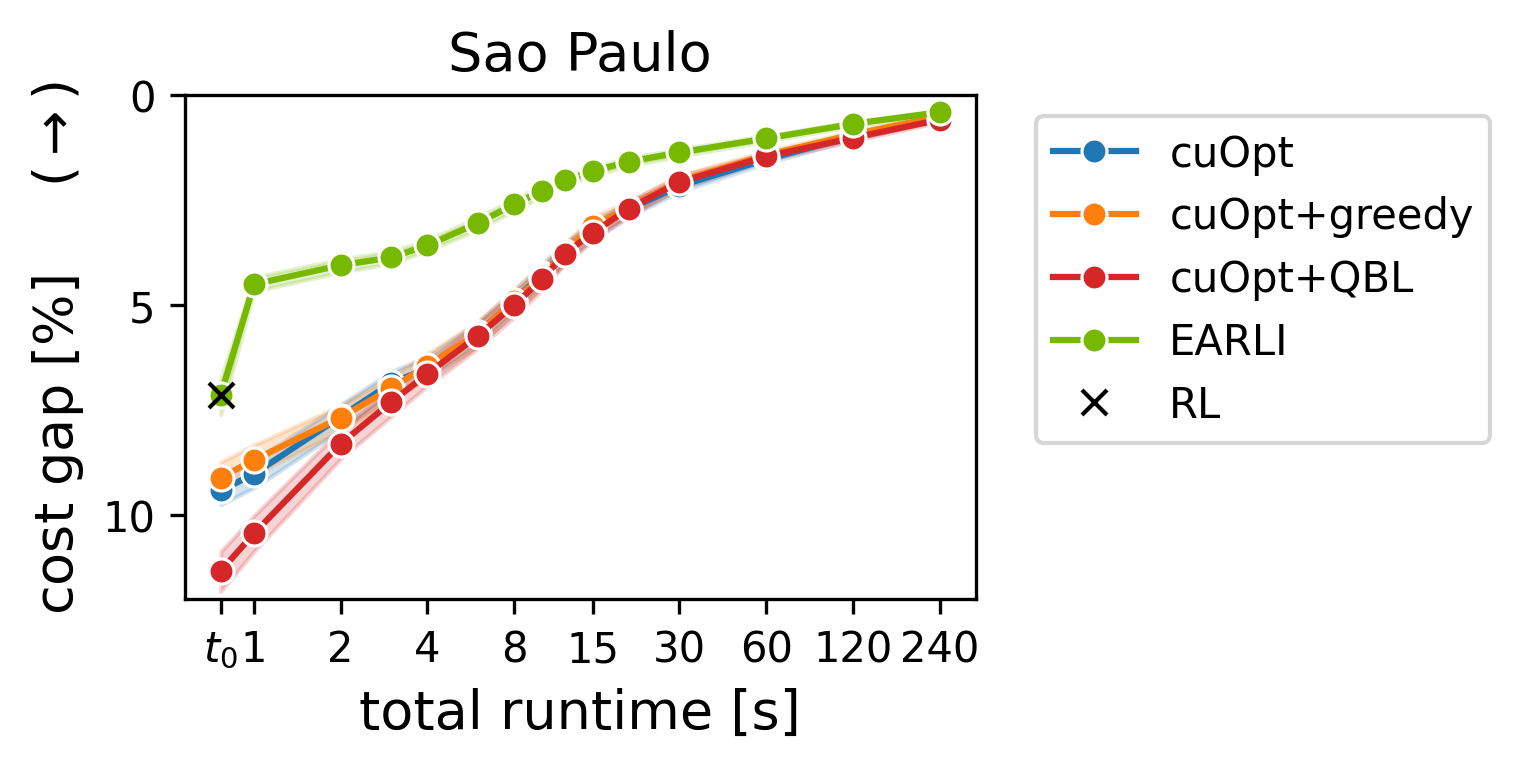
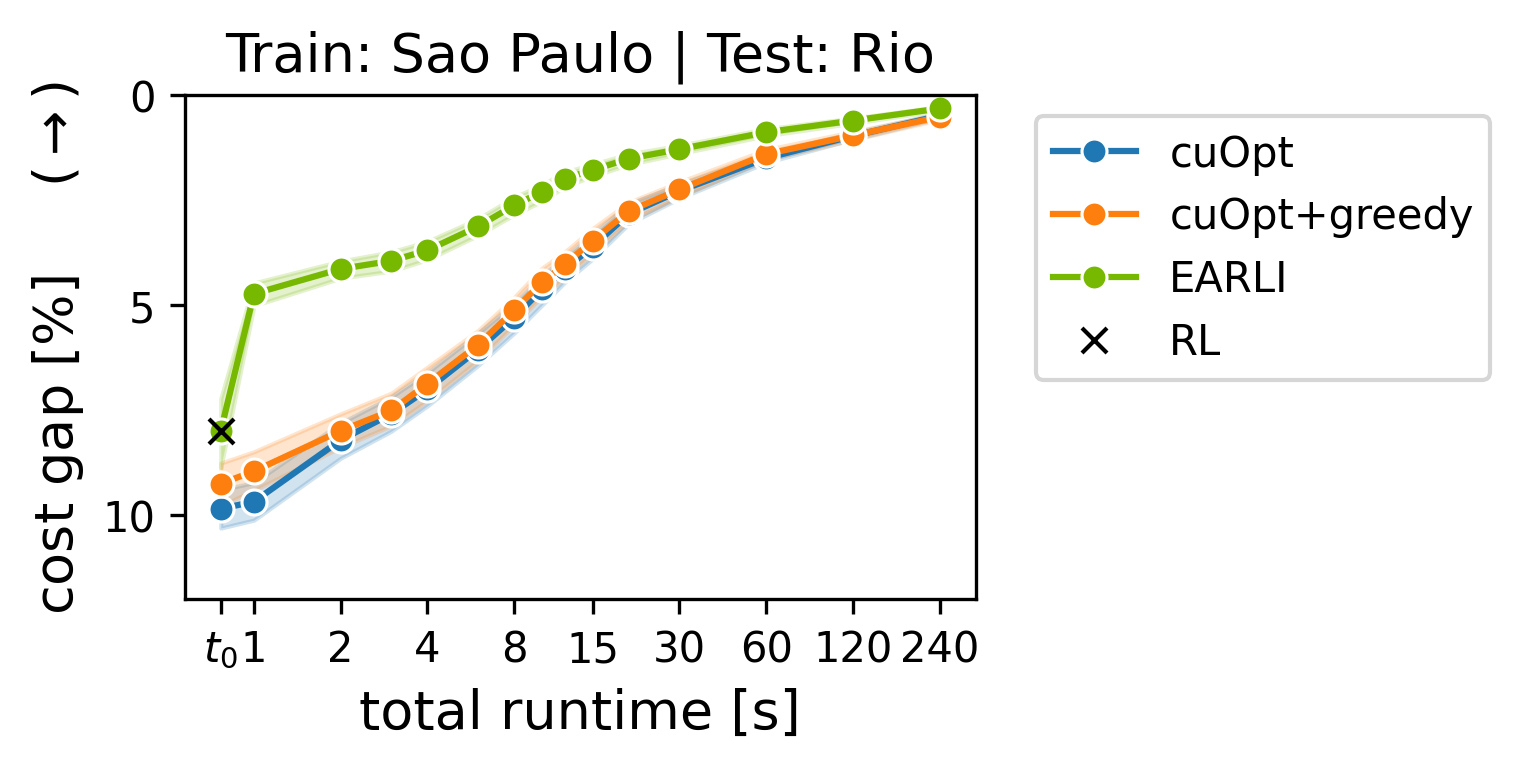
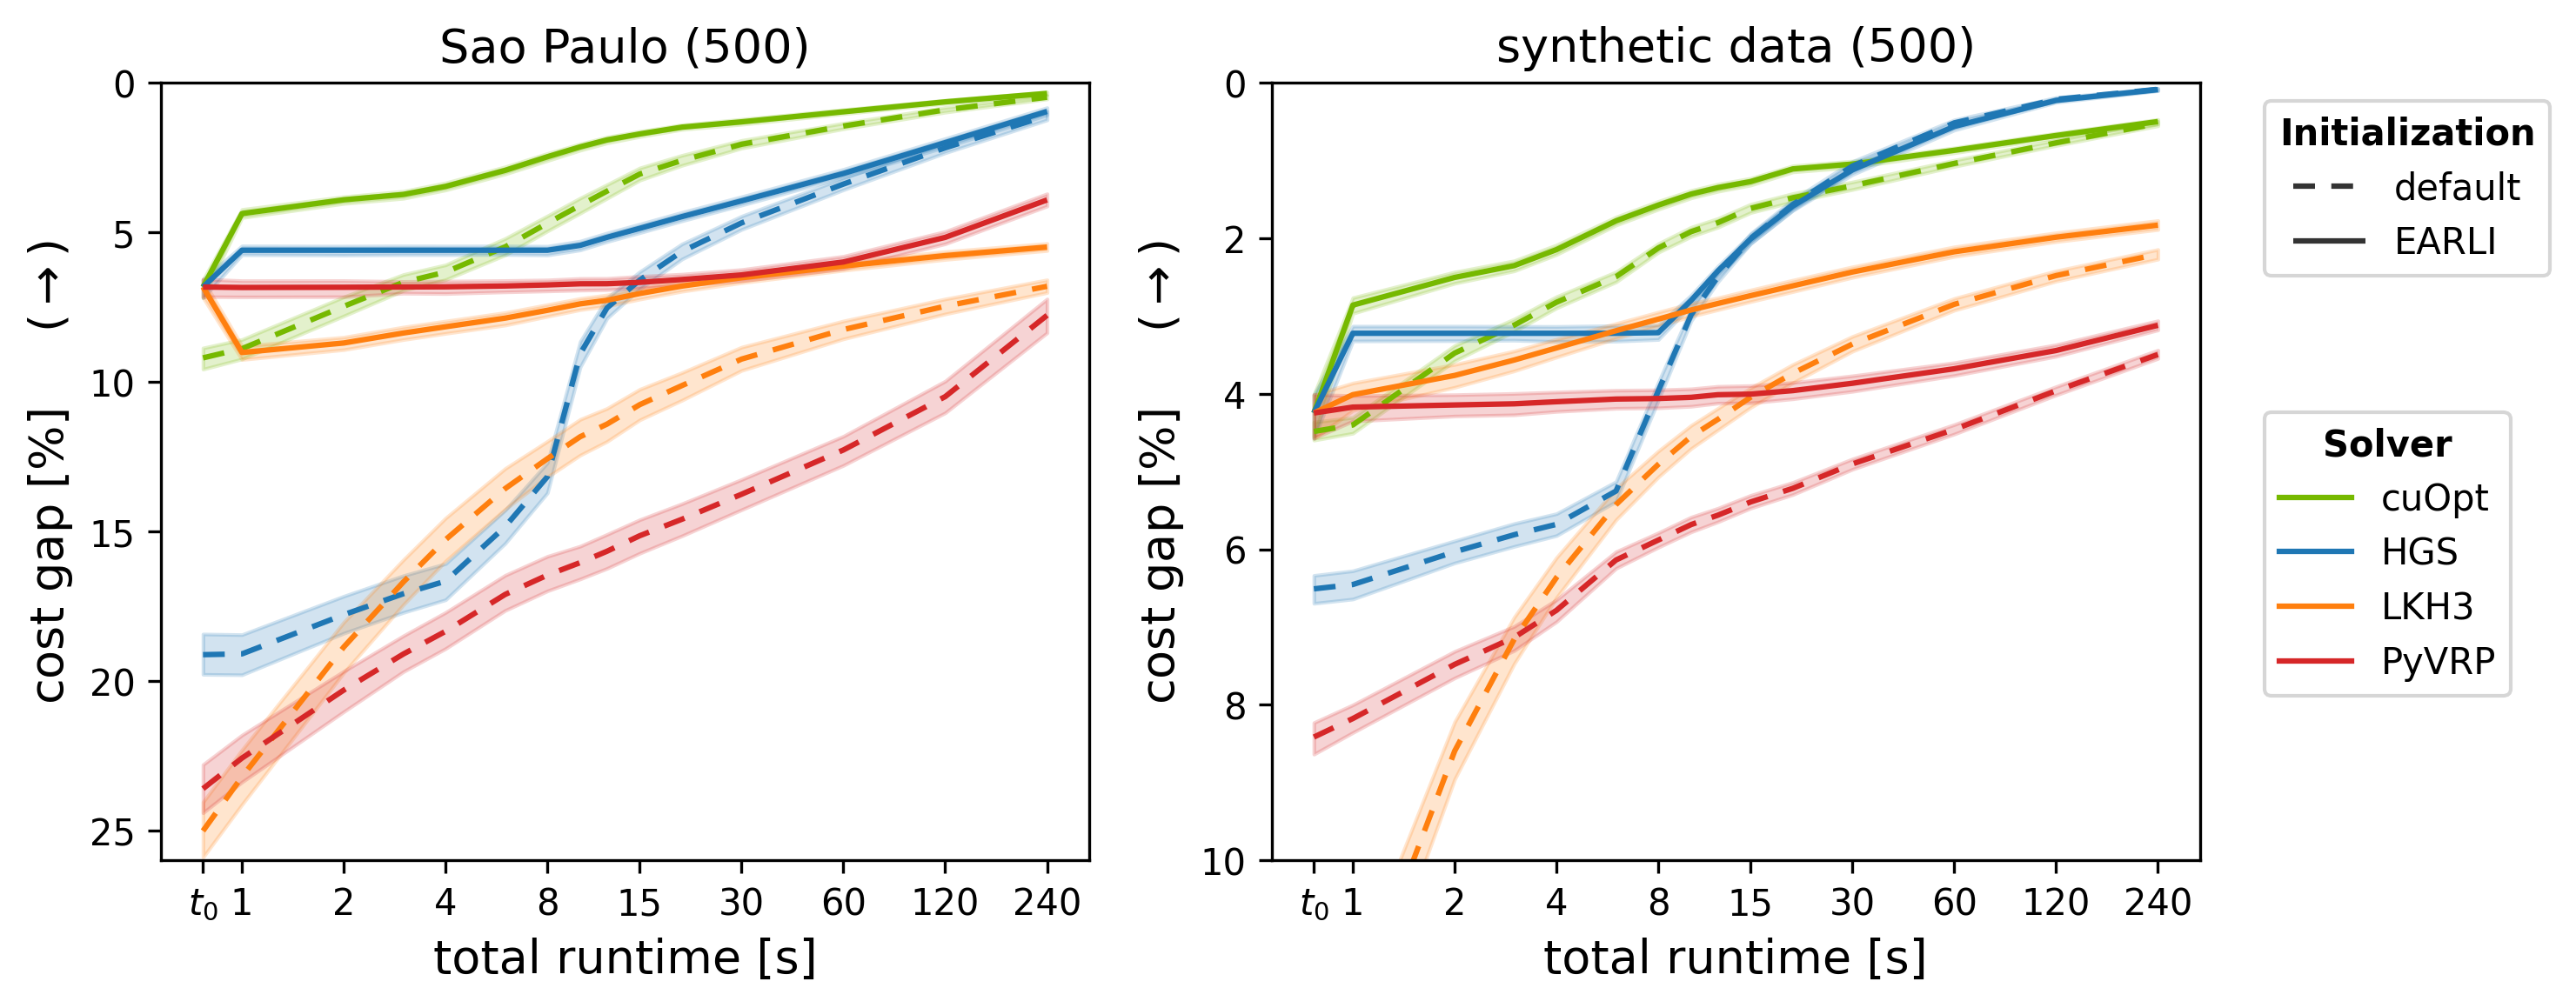
Vehicle routing problems (VRP) are an extension of the Traveling Salesperson Problem and are a fundamental NP-hard challenge in combinatorial optimization. Solving VRP in real-time at large scale has become critical in numerous applications, from growing markets like last-mile delivery to emerging use-cases like interactive logistics planning. Such applications involve solving similar VRP instances repeatedly, yet current state-of-the-art solvers treat each instance on its own without leveraging previous examples. We introduce an optimization framework where a reinforcement learning agent is trained on prior instances and quickly generates initial solutions, which are then further optimized by a genetic algorithm. This framework, Evolutionary Algorithm with Reinforcement Learning Initialization (EARLI), consistently outperforms current state-of-the-art solvers under limited time budgets. For example, EARLI handles vehicle routing with 500 locations within one second, 10x faster than current solvers for the same solution quality, enabling real-time and interactive routing at scale. EARLI can generalize to new data, as demonstrated on real e-commerce delivery data of a previously unseen city.
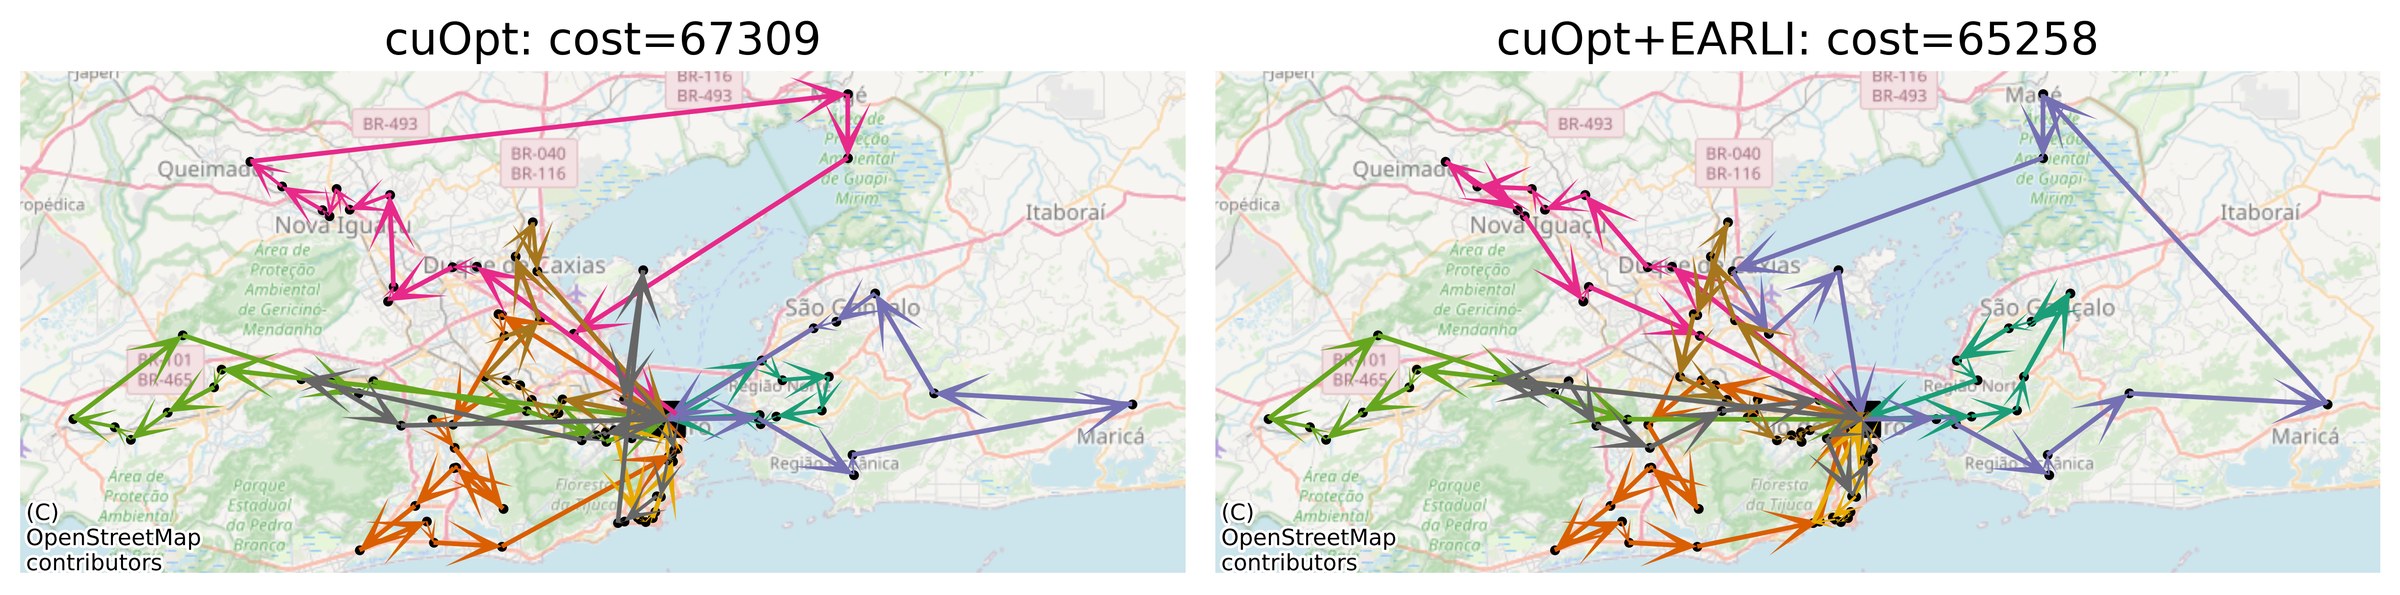
The best routing solvers today are genetic algorithms: they start from a population of random solutions and improve it step by step, from scratch for every new problem. EARLI adds learning from previous problems. A reinforcement learning agent is trained offline on past problem instances. Given a new problem, it builds a batch of complete solutions in under a second, and these solutions become the initial population of the genetic algorithm, which keeps improving them.
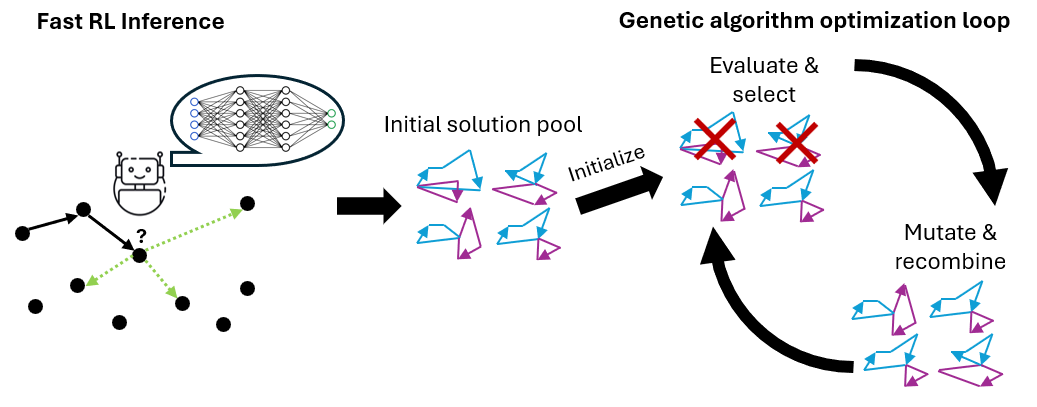
On real e-commerce delivery data from São Paulo with 500 customers, EARLI reaches within one second the solution quality that the solver alone needs about ten seconds to reach.
@article{greenberg2026earli,
title = {Reinforcement learning for initializing genetic algorithms in vehicle routing},
author = {Greenberg, Ido and Sielski, Piotr and Linsenmaier, Hugo and Gandham, Rajesh and Mannor, Shie and Fender, Alex and Chechik, Gal and Meirom, Eli},
journal = {Communications AI \& Computing},
volume = {1},
number = {1},
pages = {17},
year = {2026},
doi = {10.1038/s44488-026-00019-7}
}